---
license: apache-2.0
library_name: transformers
pipeline_tag: text-classification
tags: [laya, system-one, calibrated-decisions, rlcd, classification, routing, scoring, guardrails, moderation, reinforcement-learning, commercial-use]
---
# Laya
**Multilingual, non-autoregressive System 1 decision model.** Give it a **state** (text, email, ticket, or JSON) and **typed questions**; it returns typed answers with mathematically calibrated probabilities in a single forward pass (~33 ms) across 100+ languages. Trained with reinforcement learning against strictly proper scoring rules (**RLCD**), so reporting honest probabilities is the only way to maximise reward. It never generates text, so there is nothing to parse and nothing to hallucinate.
## Installation
```bash
pip install laya
```
Python 3.10 or newer. Optional extras: `laya[serve]` (HTTP server), `laya[mcp]` (MCP server), `laya[langchain]` (LangChain and LangGraph), `laya[onnx]` (ONNX Runtime), `laya[fast]` (TileLang GPU fast path). Platform-by-platform setup is in the [GitHub README](https://github.com/NandhaKishorM/laya#installation-details).
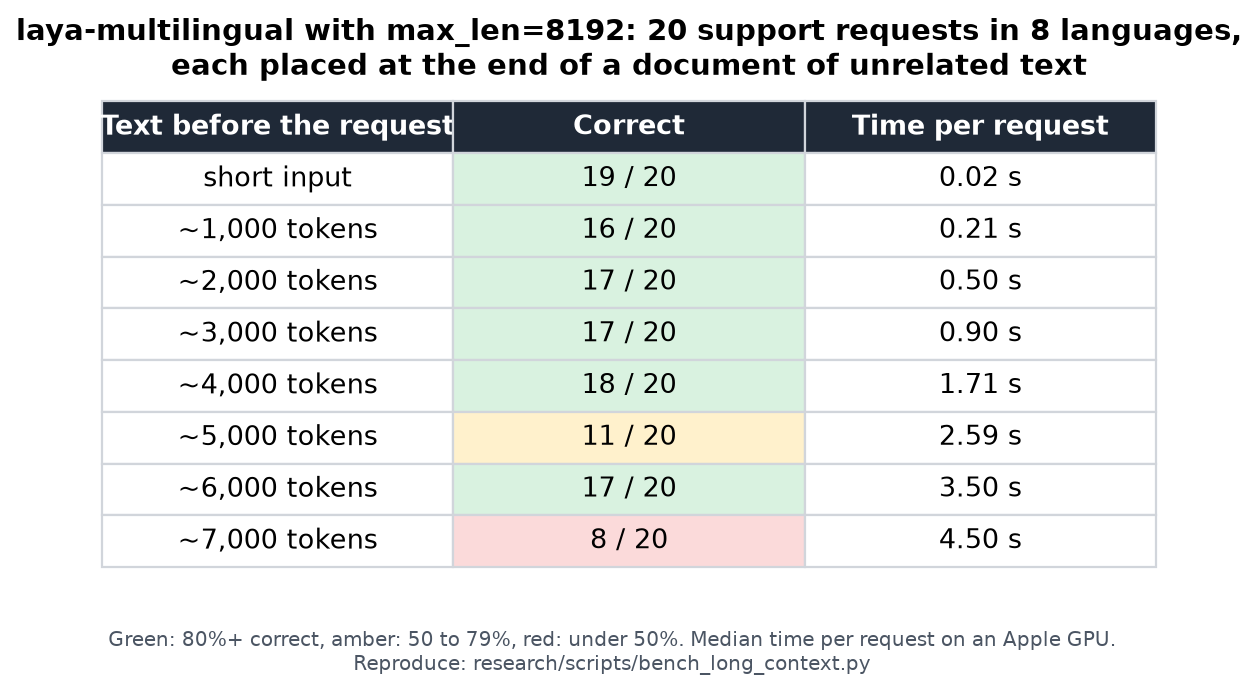
**Long documents.** `laya-multilingual` reads up to 8,192 tokens with `max_len=8192`. Measured accuracy and time by document length ([benchmark script](https://github.com/NandhaKishorM/laya/blob/main/research/scripts/bench_long_context.py)):
## Quickstart
> **Long documents: `laya-multilingual` reads up to 8,192 tokens.** It ships with a 1,024-token limit that cuts long documents off, so pass `max_len=8192` for them:
>
> ```python
> result = router.predict(long_document, questions, model="multilingual", max_len=8192)
> ```
>
> In the table above, 16 to 18 of 20 requests were answered correctly with up to about 4,000 tokens of text before them; beyond that results vary (8 to 17 of 20), so check long-document accuracy on your own data. Short inputs give identical answers with `max_len=8192`, and speed follows the input's real length, not the limit: short inputs are unchanged, and a 4,000-token input takes about 1.7 s on an Apple GPU. Name the checkpoint with `model="multilingual"`, since long mostly-English text would otherwise route to the English checkpoint.
```python
from laya import Router
router = Router() # downloads a checkpoint on first use; Router(preload=True) loads all three up front
state = "Hi, we were billed twice for March. Please refund the duplicate today or we will cancel our plan."
questions = {
"department": {"type": "choice", "instructions": "Which department should handle this?",
"criteria": {"billing": "invoices, payments, refunds",
"technical": "bugs, outages, system errors",
"other": "everything else"}},
"urgency": {"type": "score", "instructions": "How urgent is this?",
"criteria": ["not urgent", "soon", "blocking"]},
"churn_risk": {"type": "noul", "instructions": "Does the user threaten to cancel or leave?"},
}
result = router.predict(state, questions)
print(result["answers"]["department"]["choice"]) # billing
print(result["answers"]["churn_risk"]["noul"]) # probability the answer is yes
print(result["routing"]["model"]) # english
```
The same call works in any of 100+ languages. The `Router` detects the script and language and sends non-English text to `laya-multilingual`:
```python
for text in ["मुझसे मार्च में दो बार शुल्क लिया गया, कृपया डुप्लिकेट राशि वापस करें।",
"La aplicación se cierra cada vez que abro la configuración."]:
r = router.predict(text, {"department": questions["department"]})
print(r["routing"]["model"], r["answers"]["department"]["choice"])
# multilingual billing
# multilingual technical
```
## Fine-tune for better accuracy
The shipped checkpoints work zero-shot, but fine-tuning on decisions from your own domain is where accuracy jumps. On the typed-decisions benchmark (2,000 decisions across four workflows), the fine-tuned [`laya-typed-decisions`](https://huggingface.co/convaiinnovations/laya-typed-decisions) checkpoint scores **0.766** accuracy, against **0.362** for the base English checkpoint on the same decisions.
**[Fine-tuning notebook](https://github.com/NandhaKishorM/laya/blob/main/notebooks/laya_finetune_typed_decisions_2xT4_kaggle.ipynb)**: runs the whole loop on Kaggle's free 2x T4 GPUs (build the dataset, train, fit calibration temperatures, evaluate, and push the result to the Hub). Details in the [GitHub README](https://github.com/NandhaKishorM/laya#fine-tuning).
## Documentation
**[nandhakishorm.github.io/laya](https://nandhakishorm.github.io/laya/)**: guides for [prediction hooks](https://nandhakishorm.github.io/laya/hooks/), [schema-driven decisions](https://nandhakishorm.github.io/laya/structured/), [Docker](https://nandhakishorm.github.io/laya/docker/) and [LangChain and LangGraph](https://nandhakishorm.github.io/laya/langchain/), plus a full [API reference](https://nandhakishorm.github.io/laya/reference/).
## What's new in laya 0.3.20
The checkpoints themselves are unchanged. `pip install -U laya` for the latest runtime fixes:
* **Long documents with `max_len=8192`** on `laya-multilingual`: a measured table shows accuracy and time by document length.
* **Sturdier fast path.** After a CUDA out-of-memory error the fallback to CPU switches the TileLang fast path off first, a single-option `choice` no longer crashes it, and concurrent calls can no longer overwrite each other's CUDA-graph buffers.
* **Server and runtime.** `laya-serve` drains its inference pool on shutdown and returns 401 for a malformed bearer header, and `ONNXAgent` matches `Agent` on empty question sets and long conversation lists.
---
**This repo holds all three checkpoints** and is the hub for the family. The English checkpoint is at the repo root; the other two are bundled subfolders, and only the one you request is downloaded:
| Checkpoint | Backbone Encoder | Params | Context | Best at |
|---|---|---|---|---|
| **`convaiinnovations/laya`** (this repo root) | ModernBERT-large | 421M | 512 | English text, guardrails, email triage |
| [`convaiinnovations/laya-multilingual`](https://huggingface.co/convaiinnovations/laya-multilingual) | mmBERT-base | 322M | 1024 (up to 8k) | 100+ languages, ~2.2x faster |
| [`convaiinnovations/laya-typed-decisions`](https://huggingface.co/convaiinnovations/laya-typed-decisions) | ModernBERT-large | 421M | 1024 | the four typed-decisions workflows (0.766 acc) |
## Quickstart: Route Mode (Recommended)
Laya's built-in **`Router`** is the recommended way to use Laya in production. It evaluates any state in any language, automatically detects scripts and languages in sub-milliseconds, and dispatches to the optimal checkpoint in a single forward pass.
```bash
pip install laya
```
```python
import laya
from laya import Router
# Preload checkpoints into memory for instant sub-35ms routing
router = Router(preload=True)
state = {
"from": "user@acme.com",
"subject": "Duplicate charge on invoice #4411",
"body": "Hi, we were billed twice for March. Please refund the duplicate today or we will cancel our plan."
}
questions = {
"department": {
"type": "choice",
"instructions": "Which department should handle this request?",
"criteria": {
"billing": "invoices, payments, refunds",
"technical": "bugs, outages, system errors",
"sales": "pricing, new contracts",
"other": "everything else"
}
},
"urgency": {
"type": "score",
"instructions": "How urgent is this request?",
"criteria": ["not urgent", "soon", "critical deadline or blocking issue"]
},
"churn_risk": {
"type": "noul",
"instructions": "Does the user threaten to cancel or leave?"
},
"refund_requested": {
"type": "noul",
"instructions": "Does the user explicitly request a refund?"
}
}
# 1. English state -> automatically routed to ModernBERT-large (39.5 ms)
res_en = router.predict(state, questions)
print("Department :", res_en["answers"]["department"]["choice"]) # -> billing (confidence: 0.94)
print("Routing :", res_en["routing"]["model"]) # -> english
# 2. Hindi state -> automatically routed to mmBERT-base (100+ languages, 32.8 ms)
res_hi = router.predict({"body": "मुझसे दो बार शुल्क लिया गया, कृपया पैसे वापस करें।"}, questions)
print("Department :", res_hi["answers"]["department"]["choice"]) # -> billing (confidence: 0.86)
print("Routing :", res_hi["routing"]["model"]) # -> multilingual
# 3. Explicit override when you already know the checkpoint
res_td = router.predict(state, questions, model="typed-decisions")
```
Every result carries full routing metadata explaining why the choice was made:
```python
res_hi["routing"]
# {
# 'model': 'multilingual',
# 'repo': 'convaiinnovations/laya/multilingual',
# 'reason': 'non-Latin script (devanagari, 100% of letters); the English checkpoint cannot read it'
# }
```
### Why Route: The Evidence
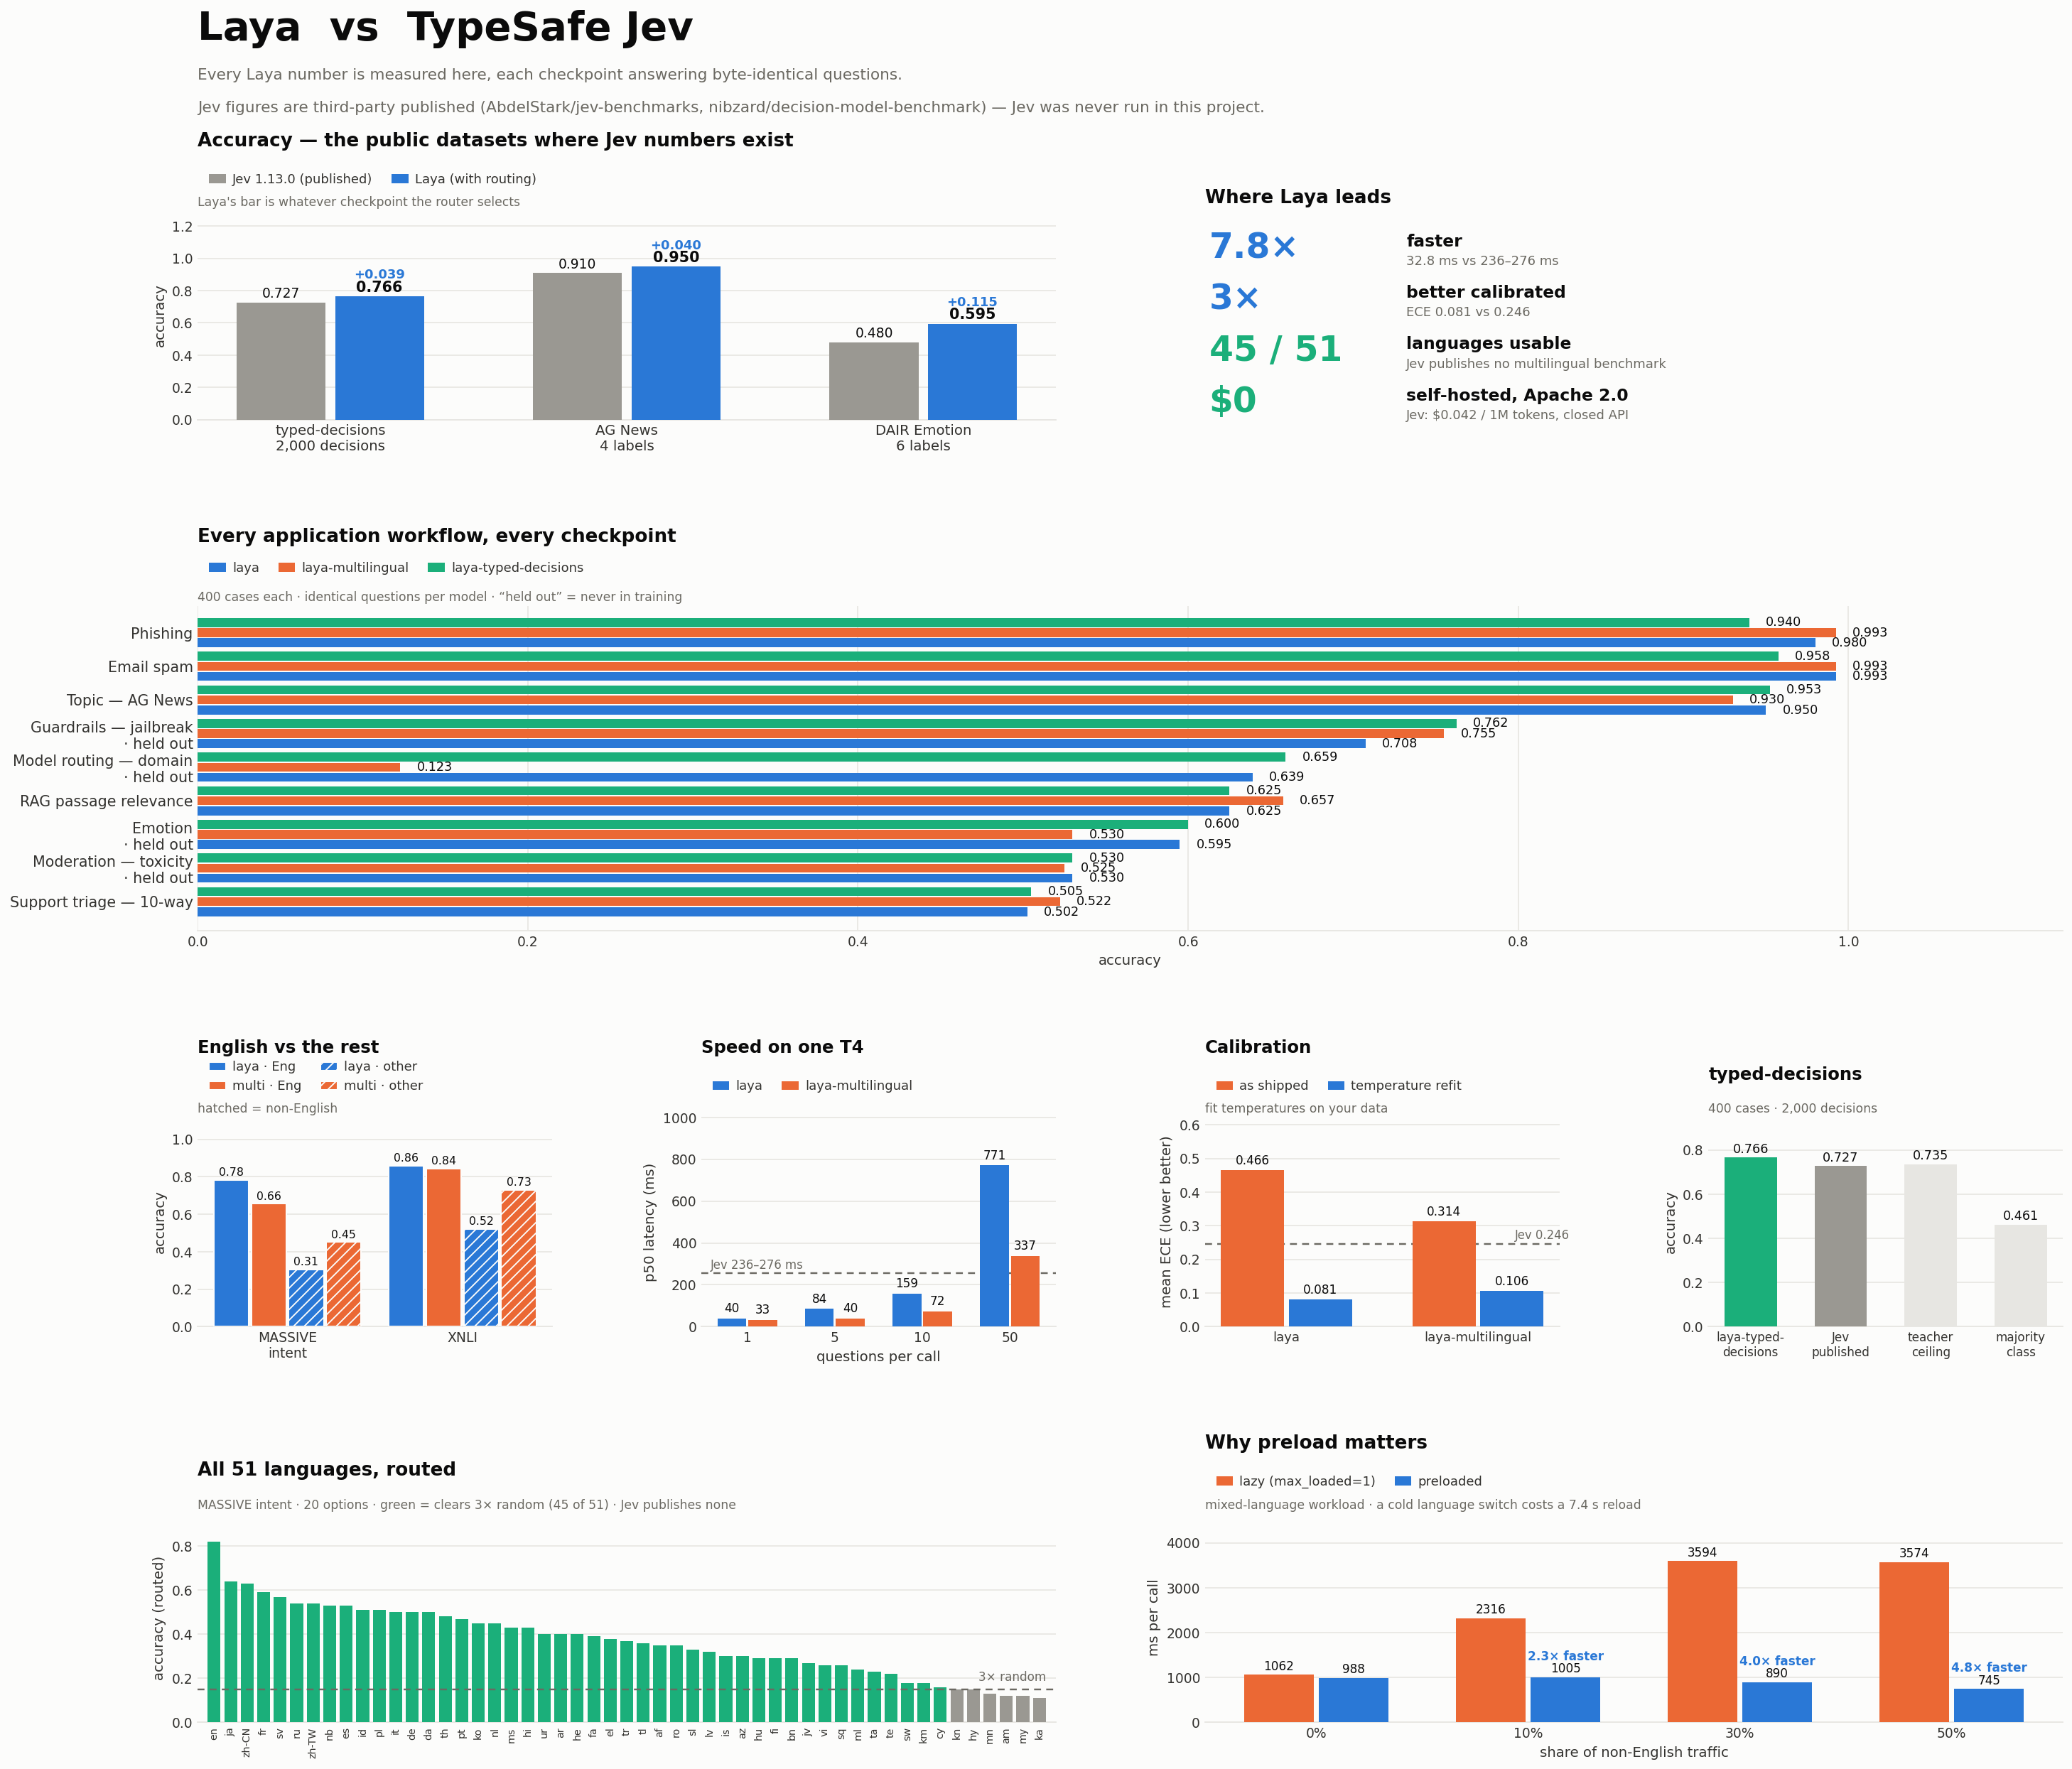
On a shared benchmark (17,416 questions, one T4 GPU, identical questions per model):
| Benchmark / Task | English (`laya`) | Multilingual (`laya-multilingual`) | `Router` (Routed) |
|---|---|---|---|
| MASSIVE intent, English | **0.783** | 0.657 | **0.783** |
| MASSIVE intent, 13 other languages | 0.306 | **0.451** | **0.451** |
| XNLI, English | **0.860** | 0.843 | **0.860** |
| XNLI, 14 other languages | 0.521 | **0.731** | **0.731** |
| Languages usable (>3x random) | 23 / 51 | 45 / 51 | **45 / 51** |
| Latency, 1 question (T4 GPU) | 39.5 ms | **32.8 ms** | **32.8 ms** |
| Latency, 10 questions batched | 158.6 ms | **72.3 ms** | **72.3 ms** |
The English checkpoint collapses on non-Latin scripts (Khmer scores **0.000 accuracy at 0.952 confidence**). Because the model stays confident while being wrong, confidence gating cannot save you. `Router` detects the script in <0.5 ms pure Python before the forward pass.
### Supplying your own language detection
If you already run a language-identification model, pass its answer instead of relying on the built-in heuristic. `lang_guess` takes a language code or a callable, is checked after an explicit `lang=` and before detection, and a callable that returns `None` falls through to detection:
```python
router.predict(state, questions, lang_guess="ro") # a code you already know
router = Router(preload=True, lang_guess=my_lid) # or install one for every request
```
### Production Preload & Memory
A cold checkpoint build costs seconds; language detection costs microseconds. The lazy default keeps **two** checkpoints resident (`english` and `multilingual`, the only two automatic routing chooses between), so after each language's first load a switch costs detection only. A single-language deployment never builds the second. `max_loaded=1` rebuilds on every switch (measured at a 7.4 s median reload on CPU and 10.3 s on T4).
For a server or a demo, preload:
```python
# Every checkpoint resident in memory; language flips cost detection only (<1 ms)
router = Router(preload=True)
router = Router(preload=True, device="cuda")
# Or preload only the specific checkpoints you serve:
router.preload(["english", "multilingual"])
# If your app already built an agent, attach it to avoid duplicate VRAM:
router.attach("english", existing_agent)
# Manage resident memory (default keeps two hot: english + multilingual, LRU eviction)
router = Router(max_loaded=3) # all three hot, e.g. with auto_task_detection
router = Router(max_loaded=1) # memory-constrained host, reloads on every switch
router.unload() # free memory
with Router() as r: # releases the models when the block ends
r.predict(state, questions)
```
| Deployment Mode | Per-Request Latency | Model Reloads |
|---|---|---|
| `Router()` (lazy, `max_loaded=2`) | detection only (<1 ms) after each language's first load | 1 the first time a language appears |
| `Router(max_loaded=1)` | 7 to 10 s on every language switch | 1 per switch |
| `Router(preload=True)` | **32.8 ms (GPU) / 193–464 ms (CPU)** | **none** |
---
## Single-Model Mode (Direct SDK)
If you only need a single checkpoint for a dedicated pipeline:
```python
import laya
# 1. Load from the repo root or subfolders (downloads only the requested weights)
agent = laya.load("convaiinnovations/laya") # English root (~808 MB)
agent_ml = laya.load("convaiinnovations/laya", subfolder="multilingual") # 100+ languages (~647 MB)
agent_td = laya.load("convaiinnovations/laya", subfolder="typed-decisions")
# 2. Run all questions in ONE single forward pass (~35 ms on GPU)
result = agent.predict(state, questions)
answers = result["answers"]
print("Department :", answers["department"]["choice"]) # -> billing (confidence: 0.94)
print("Urgency :", answers["urgency"]["score"]) # -> 1.84 / 2.0
print("Churn Risk :", answers["churn_risk"]["noul"]) # -> 0.892 (89.2% probability)
```
> **If `laya.load()` hangs:** `transformers` probes for TensorFlow at import, and when TF is
> installed its abseil runtime can deadlock model construction. Run with `USE_TF=0`.
---
## Self-hosting: Jev-compatible HTTP server
`laya-serve` exposes the `Router` on the same `POST /v1/systemone` request and response shape as TypeSafe Jev, so existing TypeSafe clients work by changing their base URL:
```bash
pip install "laya[serve]"
LAYA_DEVICE=cuda LAYA_PRELOAD=1 laya-serve # 0.0.0.0:8000, preloads the checkpoints
```
```bash
curl -s localhost:8000/v1/systemone -H 'Content-Type: application/json' -d '{
"state": {"document": "I was charged twice. Please fix this ASAP."},
"questions": {"billing": {"type": "noul", "instructions": "Is this ticket about billing?"}}
}'
```
It accepts every question shape the Jev API does (for example `criteria` as a list), ignores unknown fields, and returns a 422 naming the problem for a malformed question. It binds `0.0.0.0` with no authentication unless `LAYA_API_KEY` is set, in which case it requires `Authorization: Bearer `.
---
## Architecture
- **Backbone:** ModernBERT-large (395M, bidirectional, fully fine-tuned) + a decision head trained from scratch: 2 transformer layers, an option-marker scorer, and an act/escalate head. 421M total. (Multilingual uses mmBERT-base, 22 layers, 256k vocab, 322M total).
- **Option markers:** Every option is scored at its own `[MASK]` token, then softmaxed over that question's options. The answer space is defined at request time, so new schemas need no retraining.
- **Budget:** 512 tokens per question for English (`head_max_len = 192`); 1024 tokens for multilingual (`head_max_len = 256`).
- **Batching:** Every question in a call is answered in one single forward pass.
---
## Training
**RLCD (Reinforcement Learning for Calibrated Decisions).** The policy reports a distribution; exploration adds zero-mean Gaussian noise to the logits; the reward is a strictly proper scoring rule (log + spherical, plus ranked probability score for ordinal questions). Expected reward is maximised only by reporting honest probabilities. Updates are REINFORCE with a group-mean baseline (GRPO-style). Multi-turn conversations use TD(λ=1.0) over prefix slices.
---
## Benchmarks
Measured on a Tesla T4; every checkpoint answered byte-identical questions in the same run.
### Speed
| questions per call | `laya` | `laya-multilingual` |
|---|---|---|
| 1 | 39.5 ms | **32.8 ms** |
| 5 | 84.5 ms | **40.1 ms** |
| 10 | 158.6 ms (15.9 ms/q) | **72.3 ms (7.2 ms/q)** |
| 50 | 771 ms | **337 ms (6.8 ms/q)** |
103–332 questions/sec batched on a single T4. For reference, TypeSafe Jev has been independently measured at 236–276 ms p50 ([AbdelStark](https://github.com/AbdelStark/jev-benchmarks), [nibzard](https://github.com/nibzard/decision-model-benchmark)), so Laya answers a single question roughly **6–8× faster**.
### Laya (with routing) vs TypeSafe Jev
Every Laya figure is what `Router().predict(...)` returns — the checkpoint the router selects for that input. Jev figures are **third-party published, never measured here** (no TypeSafe API access); sample sizes and prompts differ.
| Benchmark / Metric | TypeSafe Jev 1.13.0 | Laya (routed) | Comparison |
|---|---|---|---|
| typed-decisions, 2,000 decisions | 0.727 | **0.766** | +0.039 (beats 0.735 teacher ceiling) |
| AG News, 4 labels | 0.910 | **0.950** | +0.040 |
| DAIR Emotion, 6 labels | 0.480 | **0.595** | +0.115 |
| Banking77 (72 vs 77 labels) | **0.870** | 0.425 | Jev leads on >20 options |
| ECE *(lower better)* | 0.246 | **0.081** | 3× better (post-temperature) |
| p50 latency, 1 question | 236–276 ms | **32.8 ms** | 7.8× faster |
| Languages usable (>3x random) | *no published benchmark* | **45 of 51** | Global language coverage |
| Weights | closed API | **Apache 2.0** | Open weights, on-premise capable |
| Cost | $0.042 / 1M tokens | **$0 self-hosted** | 100% free |
On DAIR Emotion, Jev assigned zero probability to the true label on 16% of examples.
#### Where Jev leads
* **High-cardinality label spaces (>20 options at default settings):** On Banking77, Jev scores 0.870 (on 72 labels) while Laya scores 0.425 (on 77 labels at default 256-token head budget). Options share a fixed `head_max_len` budget (192 tokens on English, 256 on multilingual), so 77 options receive only ~3 to 4 tokens per label, causing text to become indistinguishable. Jev supports up to 255 options out-of-the-box. While `laya-multilingual` supports 1,024 context (and up to 8,192 in the encoder) and you can raise `agent.cfg["head_max_len"] = 512` at runtime, Jev is currently better suited for 50+ options in a single prompt without tuning.
* **Soft distribution matching:** On typed-decisions, while Laya achieves higher argmax accuracy (0.766 vs 0.727), Jev achieves higher soft accuracy (0.580 vs 0.471) against the teacher's full probability distributions.
* **Out-of-the-box raw calibration:** Before temperature scaling, the base checkpoint has higher raw ECE (0.213 vs 0.144). Laya achieves its 0.081 ECE after domain temperature fitting.
Full report: [BENCHMARKS.md](https://github.com/NandhaKishorM/laya/blob/main/BENCHMARKS.md).
### typed-decisions, measured on all three checkpoints
400 cases, 2,000 decisions, four workflows — measured here.
| model | accuracy | soft acc | Brier | ECE | score MAE |
|---|---|---|---|---|---|
| **`laya-typed-decisions`** | **0.766** | 0.471 | **0.062** | 0.213 | **0.242** |
| `laya` | 0.362 | 0.332 | 0.316 | 0.175 | 0.694 |
| `laya-multilingual` | 0.342 | 0.326 | 0.439 | 0.285 | 0.687 |
| *Jev 1.13.0 (published)* | *0.727* | *0.580* | *0.148* | *0.144* | *0.391* |
| *teacher self-agreement ceiling* | *0.735* | | | | |
| *per-question majority class* | *0.461* | | | | |
The fine-tuned checkpoint clears the teacher ceiling and wins all four workflows: invoice processing 0.804, security incidents 0.766, customer service 0.764, agent-trace observability 0.730. By primitive: `noul` 0.857, `choice` 0.733, `score` 0.723.
The base checkpoints sit below the majority-class baseline here — the capability on this benchmark comes from fine-tuning, which is what the [fine-tuning notebook](https://github.com/NandhaKishorM/laya/blob/main/notebooks/laya_finetune_typed_decisions_2xT4_kaggle.ipynb) is for.
---
## Honest Limits
- **Base checkpoints are near chance on typed-decisions zero-shot** — 0.362 here and 0.352 for multilingual, against a 0.318 random and 0.461 majority-class baseline. The 0.766 belongs to the checkpoint fine-tuned on that benchmark's own training split. Laya is a fast base to specialise, not a zero-shot decision engine.
- **High-cardinality choice questions and token budgets:** Sequences split into an option prompt budget (`head_max_len`) and the remaining document/state budget (`max_len - head_max_len`):
* `laya` (English) defaults to 512 context (`head_max_len = 192`, ~320 tokens for state).
* `laya-multilingual` and `laya-typed-decisions` default to 1,024 context (`head_max_len = 256`, ~768 tokens for state; mmBERT-base encoder supports up to 8,192 with RoPE).
At default settings, a 77-option question like Banking77 allocates only `(256 - 16) // 77` ≈ 3–4 tokens per label, causing accuracy to fall off sharply (0.425 vs Jev's 0.870). If evaluating 50+ options in a single question:
1. Raise `agent.cfg["head_max_len"] = 512` and `agent.cfg["max_len"] = 1024` (or up to 2048 / 4096 / 8192) so every option has enough tokens to remain distinct.
2. Or split large option sets into a two-step coarse-to-fine hierarchical choice.
- **Ordinal `score` questions are the weakest primitive** (SST-5 0.372).
- **`noul` can follow its option labels instead of the state, most strongly on this English checkpoint.** `noul` renders its two options as `false:` / `true:`, and here that label pair can dominate the answer, returning a confident "no" for clearly positive input ([#156](https://github.com/NandhaKishorM/laya/issues/156)). Check `noul` answers on your own data. If they look stuck, ask the same question as a two-option `choice` with neutral keys and your yes/no wording as the descriptions:
```python
{"type": "choice", "instructions": "Is this review positive?",
"criteria": {"A": "yes, the review is positive", "B": "no, the review is negative"}}
```
- **`action.act_probability` carries no usable signal yet** ([#185](https://github.com/NandhaKishorM/laya/issues/185)). It reads 1.0 for almost every input, and its raw logits run against correctness (AUROC 0.30 on 396 labelled decisions). Gate on `confidence` instead, which reaches an AUROC of 0.77 on the same items.
- **Ships over-confident:** Refitting one temperature per (question type, option count) moves mean ECE **0.466 → 0.081** (`laya`) and **0.314 → 0.106** (`laya-multilingual`). Do this on your own data before trusting the probabilities.
- **English only on root:** Use `laya-multilingual` for anything outside English.
---
## Links
- **GitHub:** https://github.com/NandhaKishorM/laya
- **PyPI:** https://pypi.org/project/laya/
- **Live Demo:** https://huggingface.co/spaces/convaiinnovations/laya-demo
- **Write-up:** [Read on Dev.to](https://dev.to/nandakishor_m_6cc0adfde9f/i-built-non-autoregressive-decision-models-a-year-ago-then-a-frontier-lab-called-it-a-18me)
Apache 2.0 · Convai Innovations