---
license: mit
language:
- en
- zh
tags:
- text-generation
- multimodal
- vision-language
- audio
- agent
- video-understanding
- long-context
- mimo_v2
- transformers
library_name: transformers
---
# MiMo-V2.6-Flash-RL
**Scaling Reinforcement Learning Toward Self-Improvement**
Technical Report
## 1. Introduction
MiMo-V2.6-Flash-RL is the efficiency-balanced checkpoint of the MiMo-V2.6 series. The series is built to **scale reinforcement learning toward self-improvement** — scaling RL compute, environment diversity, and grader compute together, so the model keeps expanding its capability frontier through exploration and feedback. Key features include:
- **Native Omnimodal + Long Horizon**: Text, image, video, and audio in one model; 1M tokens for long repositories, tool traces, and multi-session agent runs.
- **You Only RL Once**: One mixed RL run across coding, general agents, visual, and cybersecurity — not separate per-domain runs. Tasks and multiple harnesses are mixed in the same batch so capabilities reinforce each other and strategies transfer to harnesses never seen in training.
- **Scaling RL Compute**: Fully asynchronous Group Relative Policy Optimization (GRPO) on very large batches — 1,568 prompts × 16 rollouts per step, billions of tokens per update.
- **Groupwise Agentic Grading (Self-Improvement Loop)**: Binary pass/fail cannot rank passing solutions, so the reward signal itself is scaled. An agentic grader compares rollouts *within each group*: **Groupwise Reward Synthesis (GRS)** builds task-specific rubrics offline from contrasting rollouts and fuses rubric quality with test outcomes; **Groupwise Advantage Redistribution (GAR)** ranks passing trajectories online and moves advantage toward higher-quality solutions. Judged against the policy’s own samples, this closes a self-improvement loop and steers toward shorter paths and fewer tokens per task.
- **Aligned RL**: Cold start from self-correction — the model reflects on and rewrites its own misaligned turns into grounded next steps. Throughout RL, environment hardening, adversarial screening, and verifier cross-checks keep the loop honest against reward hacking.
- **Multi-Prefix Multi-Teacher On-Policy Distillation (MOPD2)**: After mixed RL, MOPD2 combines autonomous student rollouts with prefix-conditioned single-turn rollouts (Teacher-Prefix and SFT-Prefix), reusing histories from teacher trajectories and SFT demonstrations so decision points train without regenerating preceding turns — extending capabilities to hard-to-verify tasks.
## Model Summary
- **Architecture**: Sparse MoE (Mixture of Experts), 309B total / 15B activated parameters
- **Context Length**: 1M tokens
- **Modalities**: Text, Image, Video, Audio
- **Vision Encoder**: 681M-param MiMo ViT (28 layers: 24 SWA + 4 Full)
- **Audio Encoder**: 308M AudioTokenizer + 127M audio patch encoder
- **Multi-Token Prediction (MTP)**: 5-layer speculative decoder
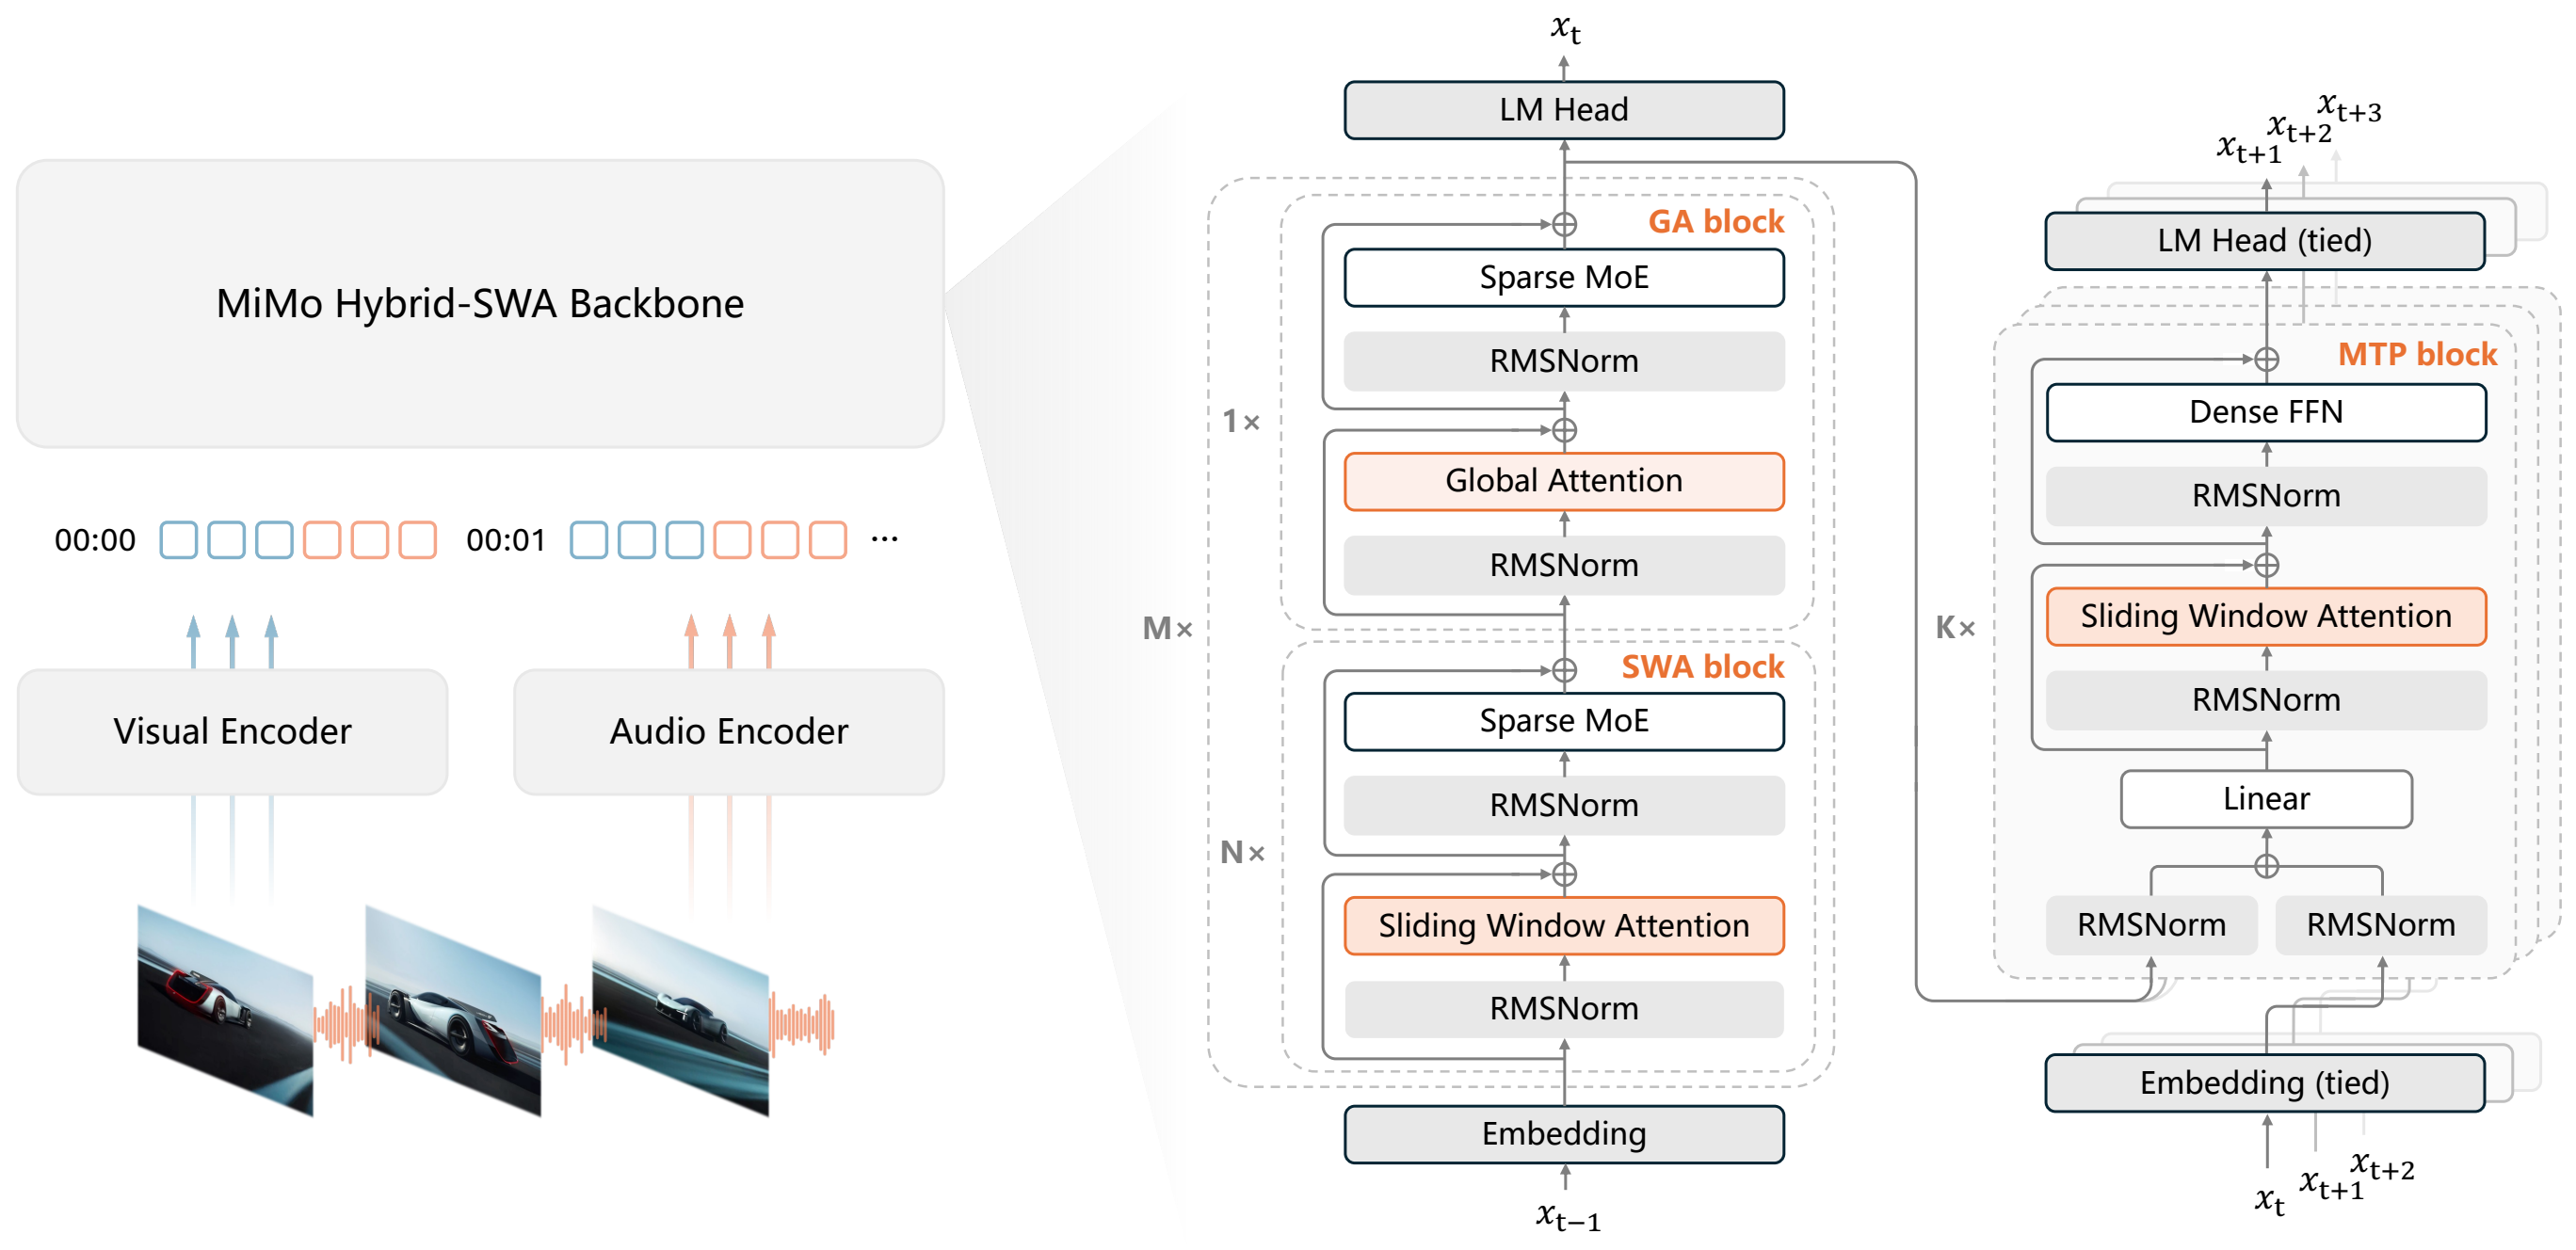
*Figure 1. MiMo-V2.6 architecture.*
## 2. Downloads
| Model | Download |
| --- | --- |
| **MiMo-V2.6-Pro-RL** | [🤗 HuggingFace](https://huggingface.co/XiaomiMiMo/MiMo-V2.6-Pro-RL) · [🤖 ModelScope](https://www.modelscope.cn/models/XiaomiMiMo/MiMo-V2.6-Pro-RL) |
| **MiMo-V2.6-Flash-RL** | [🤗 HuggingFace](https://huggingface.co/XiaomiMiMo/MiMo-V2.6-Flash-RL) · [🤖 ModelScope](https://www.modelscope.cn/models/XiaomiMiMo/MiMo-V2.6-Flash-RL) |
## 3. Evaluation Results
| Benchmark | MiMo-V2.6 Pro | MiMo-V2.6 Flash | MiMo-V2.5 Pro | Claude Opus 5 | GPT-5.6 Sol | Claude Fable 5 |
| --- | --- | --- | --- | --- | --- | --- |
| **Code Agent** | | | | | | |
| DeepSWE v1.1 | 71.9 | 67.9 | 19.0 | 74.0 | 73.0 | 70.0 |
| ProgramBench | 26.5 | 26.0 | 12.5 | 37.0 | 25.0 | 33.0 |
| MiMo Code Bench | 63.2 | 61.2 | 40.4 | 68.6 | 59.3 | - |
| **General Agent** | | | | | | |
| AutomationBench v1.0.6 | 53.1 | 52.3 | 16.0 | 50.3 | 45.8 | 46.2 |
| Toolathlon-Verified | 76.9 | 73.6 | 49.1 | 80.6 | 74.9 | 77.9 |
| GDPval-AA 2.1 | 1673 | - | 1107 | 1708 | 1588 | 1595 |
| Agents’ Last Exam | 31.6 | 27.6 | 13.2 | 31.6 | 30.8 | 25.7 |
| Terminal Bench 4.0 | 34.9 | 28.8 | 1.5 | 49.0 | 39.9 | 42.4 |
| Terminal Bench 2.1 | 89.9 | 87.6 | 65.2 | 89.1 | 88.8 | 84.3 |
| OSWorld-Verified | 82.0 | 80.8 | - | 83.4 | 83.0 | 86.0 |
| JobBench | 62.0 | 61.2 | 25.0 | 65.7 | 45.4 | 57.4 |
| **Cybersecurity** | | | | | | |
| CyberGym | 94.0 | 95.1 | 40.0 | - | - | - |
| MiMo Cyber Bench | 80.2 | 77.2 | 0.0 | - | - | - |
| ExploitGym | 17.8 | 6.0 | 0.2 | 22.1 | 30.3 | 28.4 |
| ExploitBench | 47.9 | 25.3 | 16.6 | 70.0 | 78.5 | 78.0 |
| SEC Bench Pro | 66.3 | 47.5 | 17.7 | - | 79.1 | - |
| **Visual Agent** | | | | | | |
| MiMo VisualCoding | 72.3 | 71.5 | - | 70.0 | 73.4 | 69.1 |
## 4. Model Architecture
### LLM Backbone
| Component | MiMo-V2.6-Flash-RL |
| --- | --- |
| Layers (Total / SWA / GA) | 48 / 39 / 9 |
| Hidden Size | 4096 |
| SWA Heads (Q/KV) | 64 / 8 |
| GA Heads (Q/KV) | 64 / 4 |
| Head Dimensions (QK / V) | 192 / 128 |
| Sliding Window Size | 128 |
| Routed Experts (Total / Activated) | 256 / 8 |
| Max Context Length | 1M |
| MTP / Speculative Decoder | 5 SWA layers, window 1024 |
The first Transformer block uses global attention with a dense FFN. Remaining blocks interleave local SWA and GA; both use sparse MoE FFNs without shared experts.
### Vision Encoder (MiMo ViT)
| Configuration | Value |
| --- | --- |
| Layers (Total / SWA / GA) | 28 / 24 / 4 |
| Hidden Size | 1280 |
| Attention Heads (Q / KV) | 32 / 8 |
| Head Dimension | 64 |
| Patch Size (T × H × W) | 2 × 16 × 16 |
| Sliding Window (Left / Right) | 64 / 64 |
| Spatial Merge Size | 2 × 2 |
| Parameters | 681M |
### Audio Encoders
AudioTokenizer encoder: 24 layers (12 SWA / 12 GA), hidden 1024, 20 RVQ codebooks, 308M parameters. Audio patch encoder: 6 layers, 127M parameters; four frames per patch (25 Hz → 6.25 Hz).
### Speculative Decoder
5-layer SWA MTP drafter (DFlash-style). Predicts 7 subsequent tokens per forward pass for parallel verification.
## 5. Deployment
For best performance, follow the [SGLang MiMo cookbook](https://docs.sglang.io/cookbook/autoregressive/Xiaomi/MiMo-V2.5). Docker image: `lmsysorg/sglang:latest`.
### SGLang
```bash
sglang serve \
--trust-remote-code \
--model-path XiaomiMiMo/MiMo-V2.6-Flash-RL \
--tp 8 \
--dp 2 \
--enable-dp-attention \
--enable-dp-lm-head \
--mm-enable-dp-encoder \
--mem-fraction-static 0.65 \
--chunked-prefill-size 16384 \
--speculative-algorithm EAGLE \
--speculative-num-steps 3 \
--speculative-eagle-topk 1 \
--speculative-num-draft-tokens 4 \
--enable-multi-layer-eagle \
--reasoning-parser mimo \
--tool-call-parser mimo \
--host 0.0.0.0 \
--port 30000
```
### vLLM
Follow the [vLLM MiMo-V2.5 recipe](https://recipes.vllm.ai/XiaomiMiMo/MiMo-V2.5). Stable vLLM may lag; pre-built image: `docker pull vllm/vllm-openai:mimov25-cu129`.
```bash
vllm serve XiaomiMiMo/MiMo-V2.6-Flash-RL \
--tensor-parallel-size 4 \
--trust-remote-code \
--gpu-memory-utilization 0.95 \
--max-model-len auto \
--reasoning-parser mimo \
--tool-call-parser mimo \
--enable-auto-tool-choice \
--generation-config vllm
```
Recommended sampling: `temperature=1.0`, `top_p=0.95`.
Also available in AI Studio, MiMo Code, Xiaomi MiMo Desktop, Xiaomi MiMo Open Platform API, and OpenRouter.
## Citation
```bibtex
@misc{mimo2026v26flash,
title={MiMo-V2.6-Flash-RL},
author={{Xiaomi MiMo Team}},
year={2026},
howpublished={\url{https://huggingface.co/XiaomiMiMo/MiMo-V2.6-Flash-RL}},
}
```
## Contact
For questions or feedback, reach us at [mimo@xiaomi.com](mailto:mimo@xiaomi.com) or join our community:
- [WeChat Group](https://work.weixin.qq.com/apph5/external_room/join/group_mng?plg_id=c417f99bd9014b5dd894daa8bfe19790&)
- [Discord](https://discord.gg/WX2R2uNp)
- [Telegram](https://t.me/+3T-I0pekOVIyNDBl)
- [Reddit](https://www.reddit.com/r/XiaomiMiMo_Official/)
