---
license: other
license_name: qwen-research
base_model: Qwen/Qwen-Image-2.1
library_name: diffusers
pipeline_tag: text-to-image
tags:
- qwen
- image-generation
- image-editing
- rgba
- lora
- distilled
- few-step
---


⚡ Pruna-Qwen-Image-2.1
Few-step LoRA adapters for Qwen-Image-2.1
5 or 8 steps
·
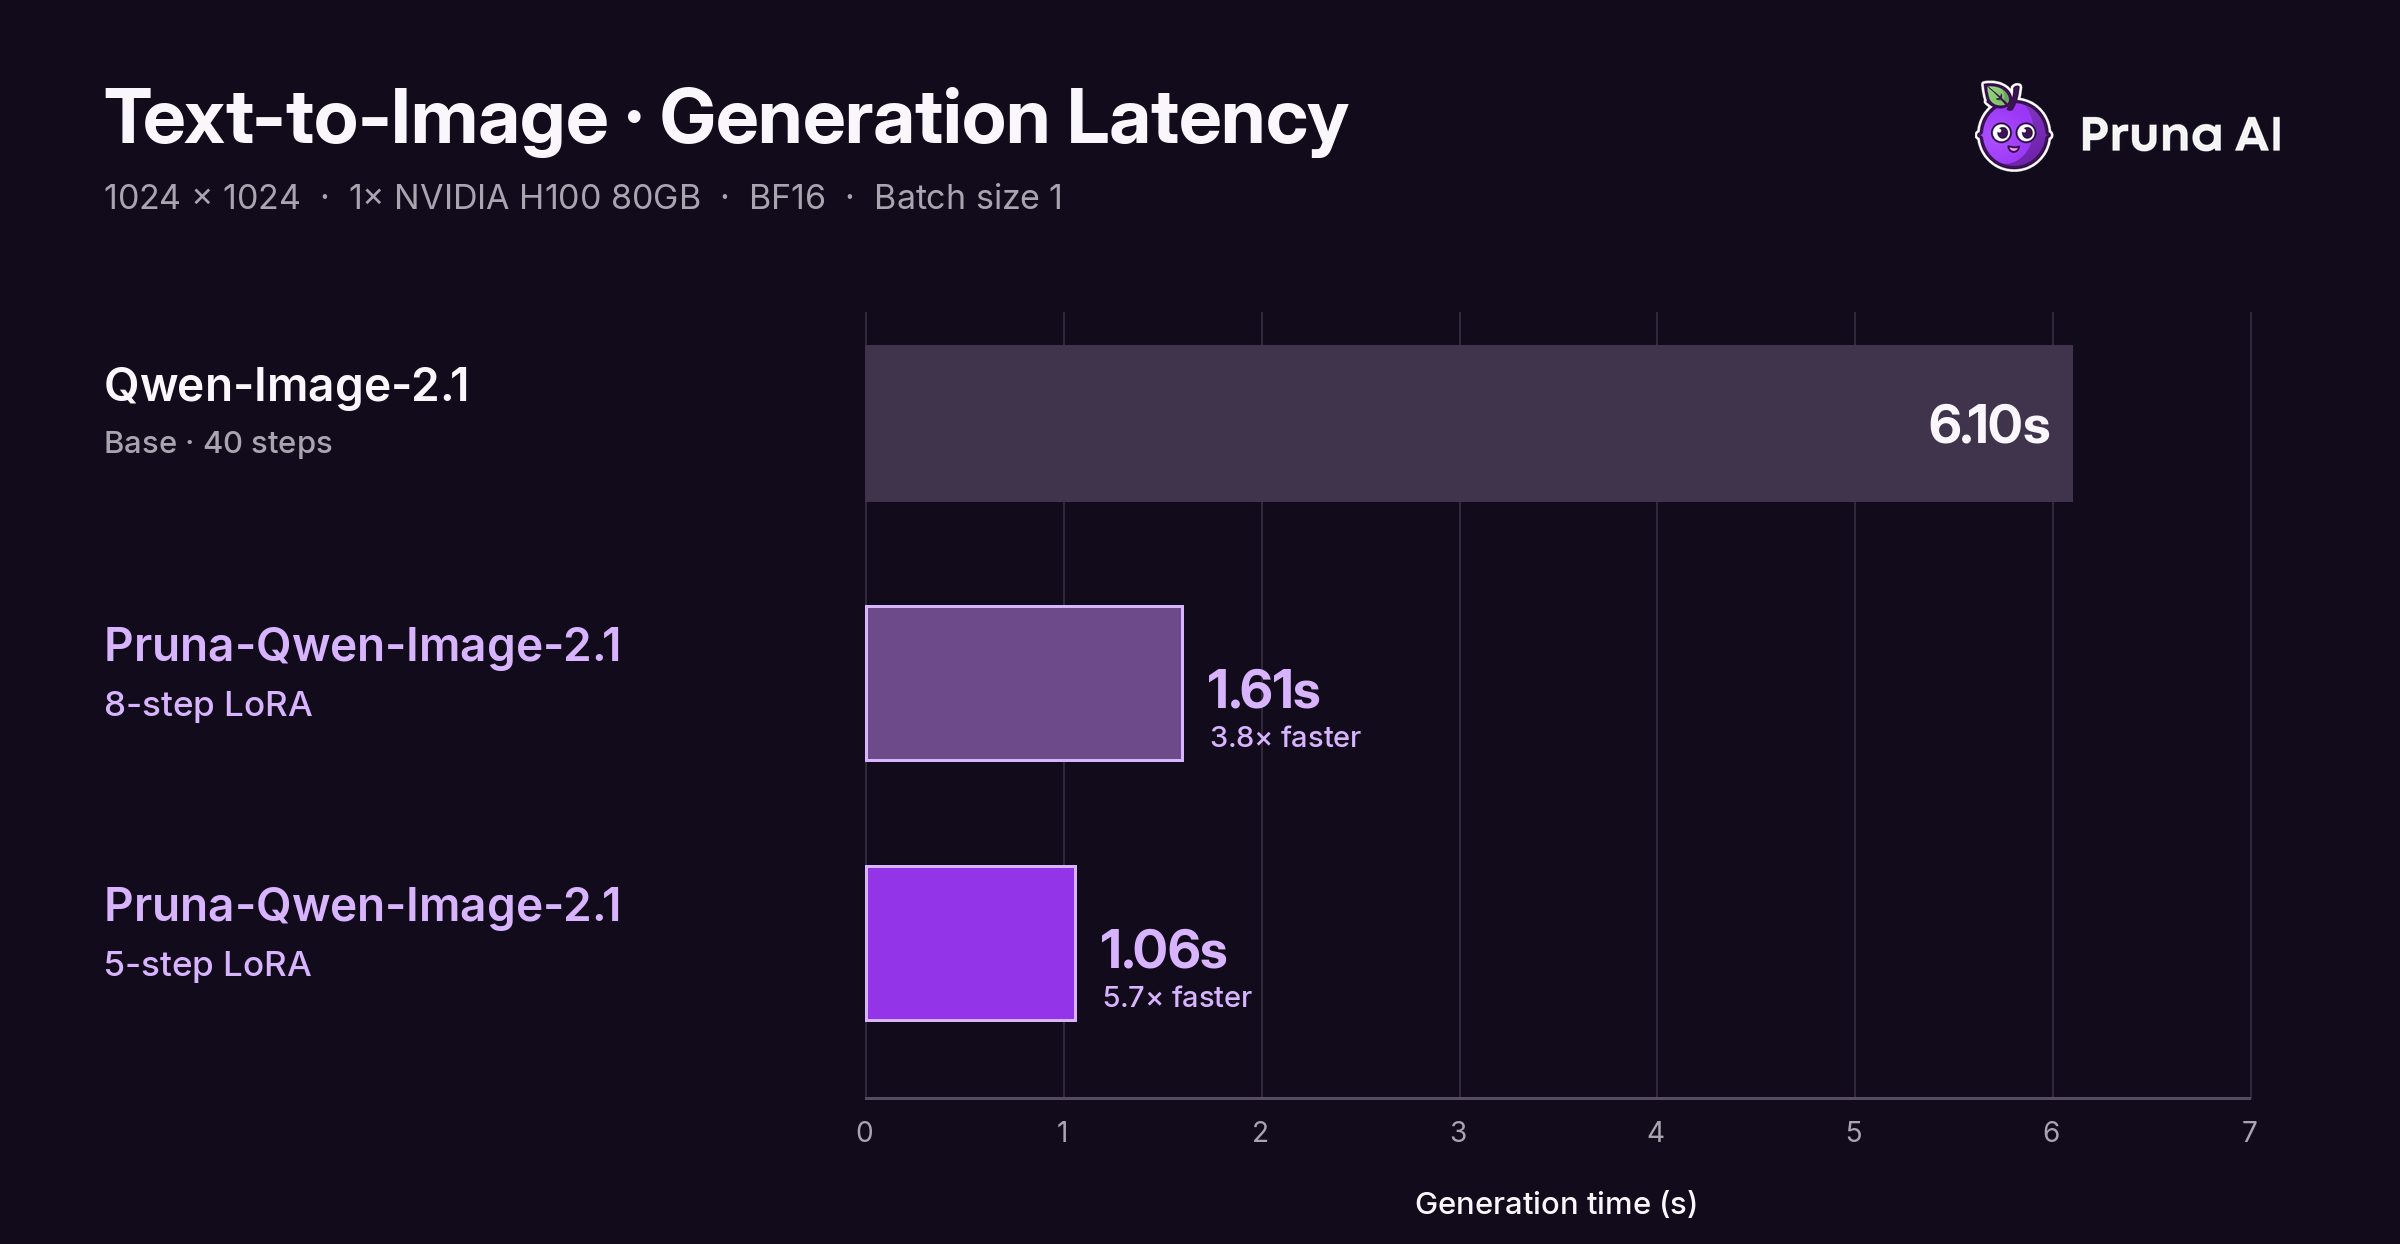
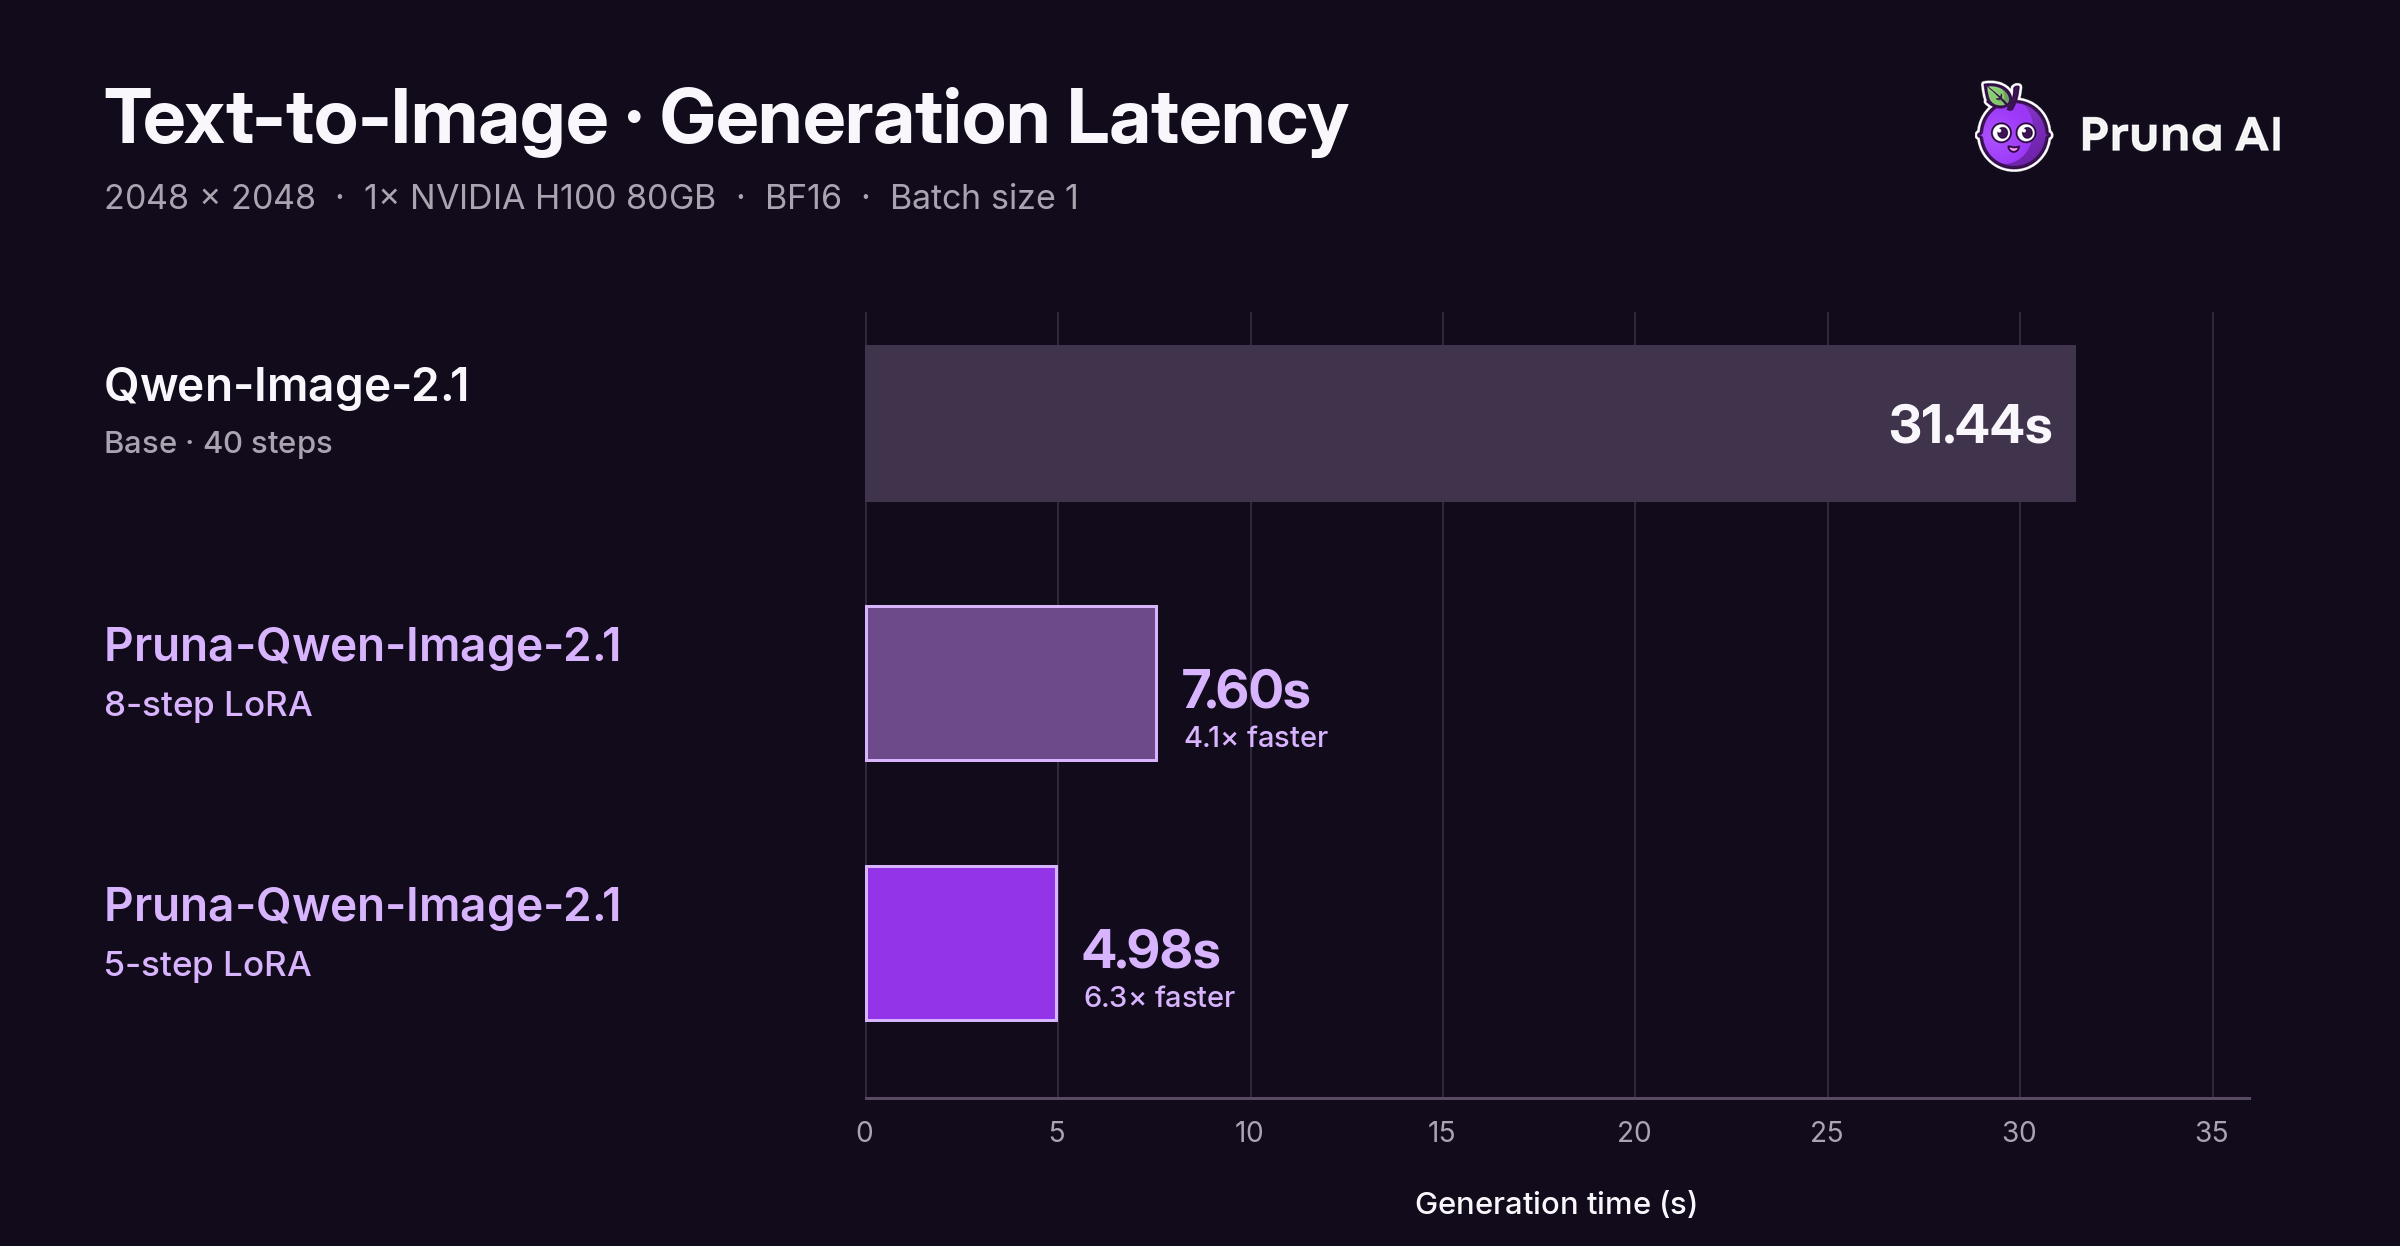
Up to 6.3x faster
·
No CFG
·
Text-to-image and image editing
**Pruna-Qwen-Image-2.1 is a set of LoRA adapters that let
[`Qwen/Qwen-Image-2.1`](https://huggingface.co/Qwen/Qwen-Image-2.1) generate
and edit images in only 5 or 8 steps. The adapters load on top of the base
model, so the pipeline, text encoder, and VAE stay unchanged. Training is based
on DMD. Improved using Qwen.**
> **v0.1: first release, work in progress.** Pruna-Qwen-Image-2.1 does not yet match the
> visual quality of the base model. We are still improving the distillation and
> will update this repository as new versions become available.
## Variants
Both adapters are v0.1. Pick one based on whether you need **quality** or **speed**.
| File | Steps | Trade-off |
|---|:---:|---|
| `p_qwen_image_2.1_8step_v0.1.safetensors` | 8 | **Higher quality.** Recommended as the default. |
| `p_qwen_image_2.1_5step_v0.1.safetensors` | 5 | **Higher speed**, with noticeably lower visual quality. |
Each adapter is trained for its own sigma schedule. Load only one at a time.
## Prompts, editing, and resolution
The adapters were trained at **1K resolution only**, with a mix of simple and
upsampled prompts, text-to-image generation, and single- and multi-image editing
with **up to 3 reference images**. Prompt upsampling is optional; detailed prompts
usually give better results.
Start at **1024 × 1024** and use at most **3 reference images** for editing.
Higher resolutions (including 2K) and more reference images may work, but are
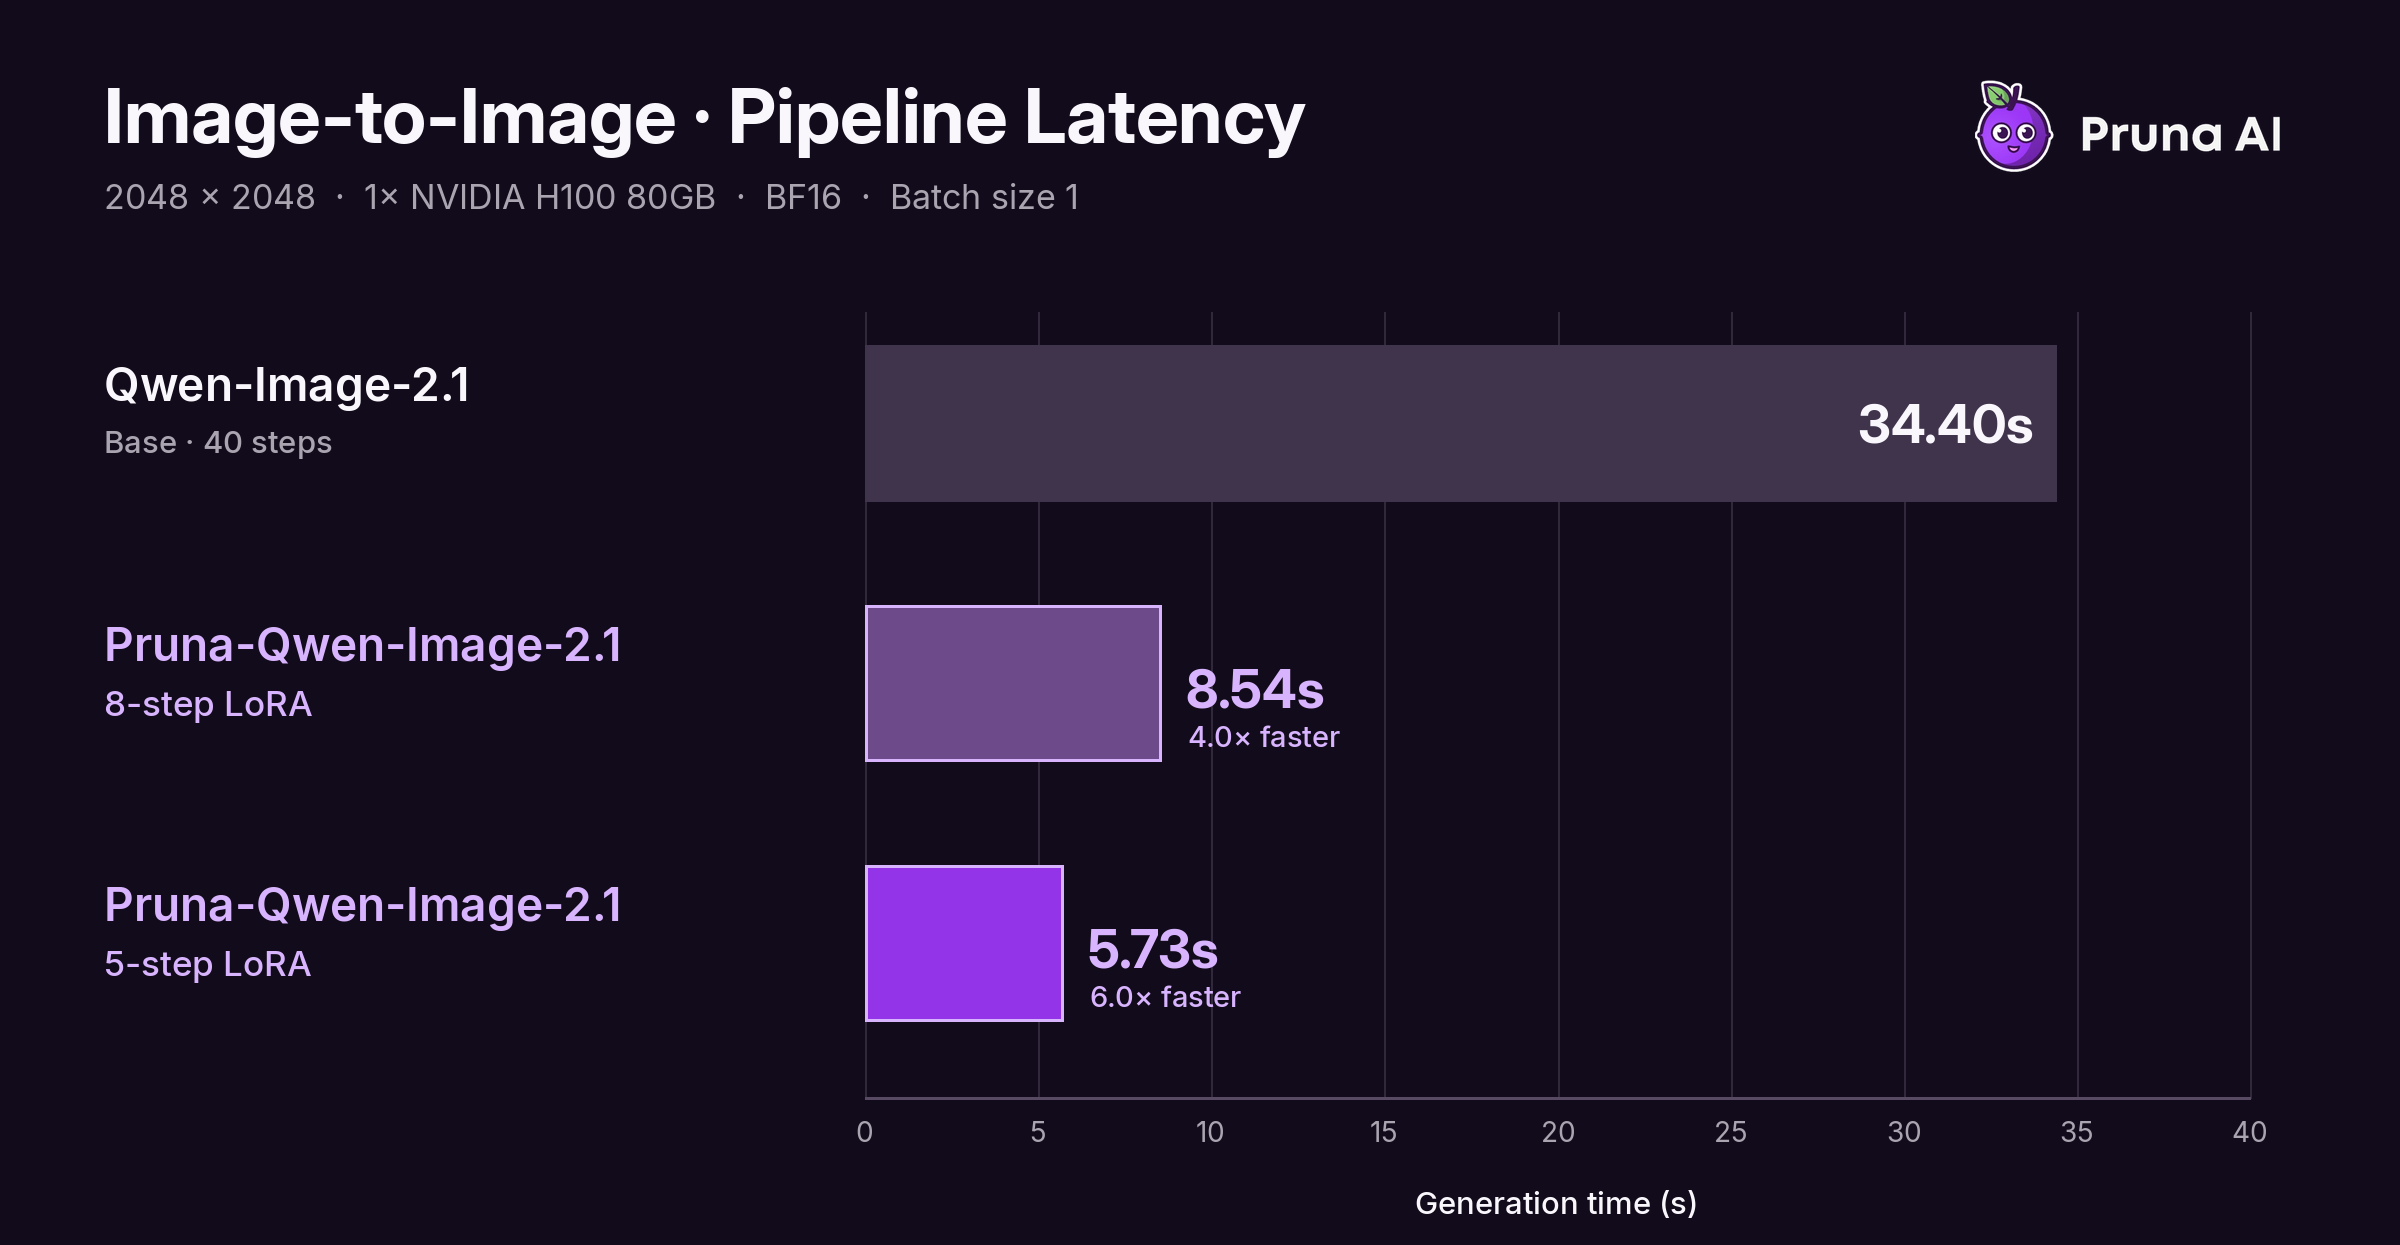
outside the training coverage, and quality may vary. The 2K timings below show
inference speed, not a guarantee of quality at that resolution.
## Benchmarking
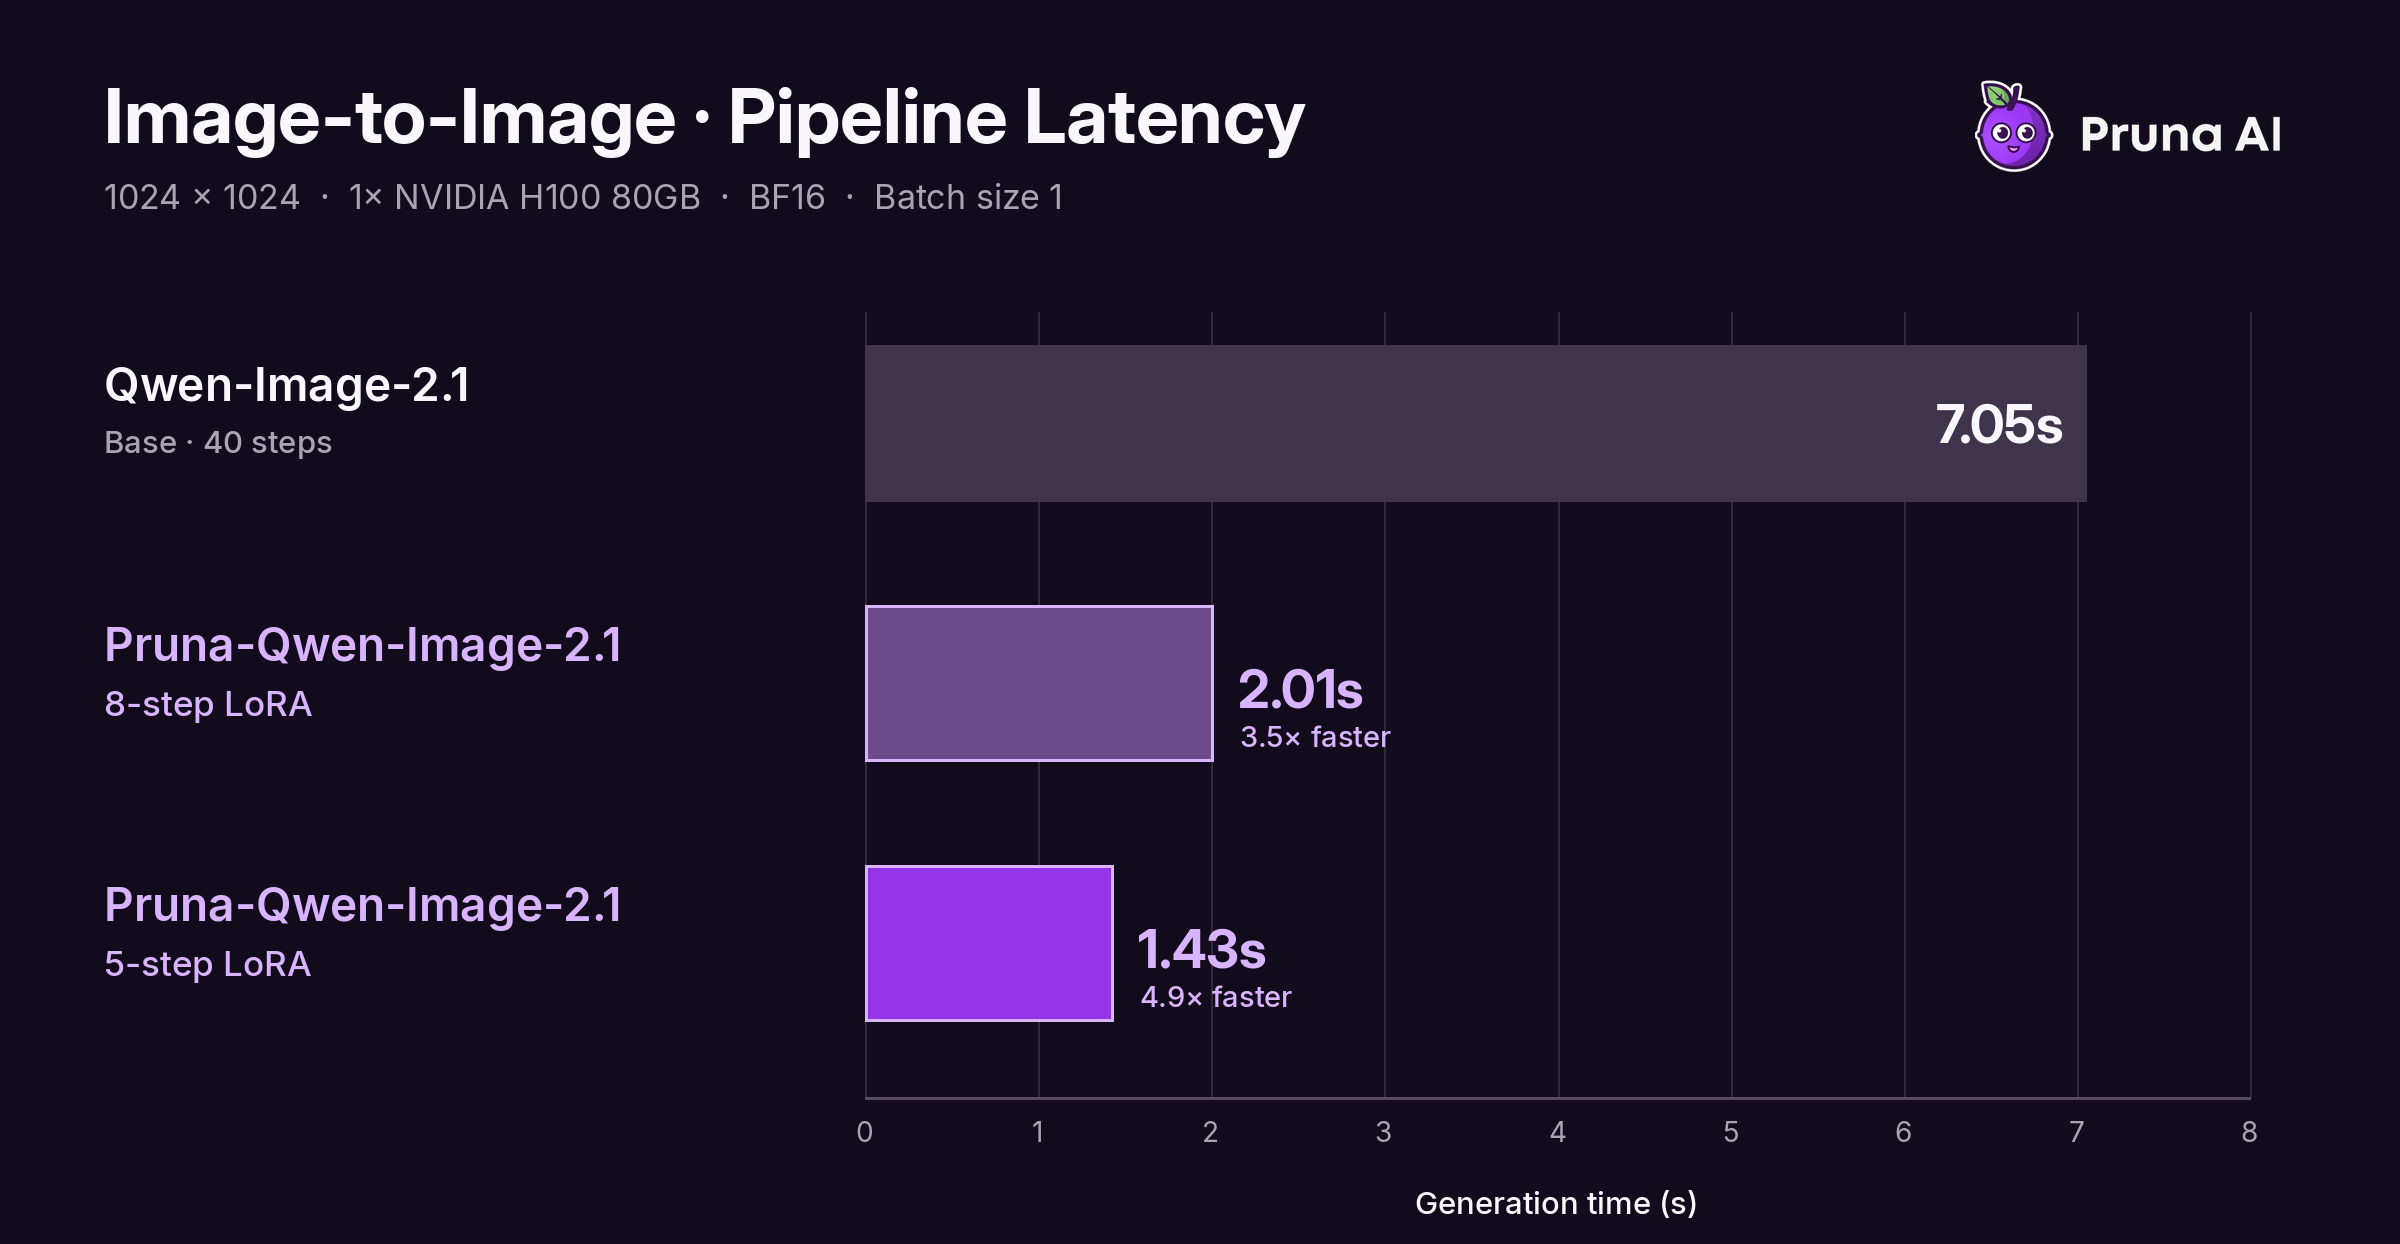
Use a table; Hugging Face can otherwise render the `![]() ` elements as separate blocks.
Text-to-image with the official Qwen model-card example prompt, BF16, batch size 1,
on one NVIDIA H100 80GB. Median of 3 requests after one warmup per configuration.
Includes prompt encoding, denoising, and decoding; excludes PNG saving, model
loading, and warmup. Base: 40 steps with KV cache on; Pruna-Qwen-Image-2.1: 5 or 8 steps with
KV cache off, as configured for this benchmark. The examples below enable KV caching for
Pruna-Qwen-Image-2.1; the chart has not been remeasured with that setting. LoRAs were unmerged;
no CFG, compilation, or CPU offload. These timings do not imply equal image quality.
## Quickstart
Runs text-to-image and image editing with the same pipeline. Needs a **CUDA GPU**.
```bash
pip install 'torch>=2.4.0' 'transformers>=5.17' accelerate peft pillow
pip install git+https://github.com/huggingface/diffusers@6256aa7666cedd47443adc8f82da9a10e110b09c
```
```python
import torch
from PIL import Image
from diffusers import FlowMatchEulerDiscreteScheduler, QwenImage21Pipeline
STEPS = 8 # 8 for higher quality, 5 for higher speed
# The terminal sigma 0 is appended by the scheduler.
SIGMAS = {
5: [1.0, 0.94, 6 / 7, 2 / 3, 0.4],
8: [1.0, 14 / 15, 6 / 7, 10 / 13, 2 / 3, 6 / 11, 0.4, 2 / 9],
}[STEPS]
pipe = QwenImage21Pipeline.from_pretrained(
"Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")
pipe.load_lora_weights(
"PrunaAI/Pruna-Qwen-Image-2.1",
weight_name=f"p_qwen_image_2.1_{STEPS}step_v0.1.safetensors",
)
# Use the sigmas exactly as given: no extra shifting.
pipe.scheduler = FlowMatchEulerDiscreteScheduler.from_config(
pipe.scheduler.config,
use_dynamic_shifting=False,
shift=1.0,
shift_terminal=None,
)
```
## For Text-to-Image
Longer, more descriptive prompts give better results.
```python
image = pipe(
prompt=(
'A glowing neon shop sign that reads "QWEN IMAGE 2.1", mounted on a brick wall '
"in a narrow city alley at night. Heavy rain, wet pavement reflecting pink and "
"blue light, shallow depth of field, cinematic photograph."
),
width=1024,
height=1024,
generator=torch.Generator("cuda").manual_seed(42),
num_inference_steps=STEPS,
sigmas=SIGMAS,
true_cfg_scale=1.0,
use_kv_cache=True,
).images[0]
```
### For Image Editing
```python
image = pipe(
prompt="Change the background to a sunset beach",
image=Image.open("input.png").convert("RGB"),
generator=torch.Generator("cuda").manual_seed(42),
num_inference_steps=STEPS,
sigmas=SIGMAS,
true_cfg_scale=1.0,
use_kv_cache=True,
).images[0]
```
### Recommended settings
- **Use the sigma schedule that matches your adapter**, and keep the scheduler
at `shift=1.0` with dynamic shifting off so the sigmas are not shifted twice.
- 8-step: `1 → 14/15 → 6/7 → 10/13 → 2/3 → 6/11 → 0.4 → 2/9 → 0`
(shift 2, computed as `σ = 2t / (1 + t)` on evenly spaced `t`)
- 5-step: `1 → 0.94 → 6/7 → 2/3 → 0.4 → 0`
- **No CFG.** Keep `true_cfg_scale=1.0` and do not pass a negative prompt.
- **Keep the LoRA strength at 1.0.**
- **Write detailed prompts for text-to-image.** Longer prompts that describe
the subject, setting, lighting, and style work noticeably better than short
ones.
## Limitations
- This is a first version. Quality is below that of the base model.
- The 5-step adapter is faster than the 8-step one, but its images are
visibly worse.
- Short or vague text-to-image prompts give weaker results.
- The adapters are only intended for the settings above. Other step counts,
schedules, or CFG values are not supported.
## What this is not
- Not a standalone model. It needs the `Qwen/Qwen-Image-2.1` base weights.
- Not a replacement for the base model when you need its full quality.
- Not a finished release. Expect the weights to change in future versions.
## License
Pruna-Qwen-Image-2.1 is a derivative of Qwen-Image-2.1 and is distributed
under the **Qwen RESEARCH LICENSE AGREEMENT**. Review its use restrictions
before using or redistributing the adapters.
Qwen is licensed under the Qwen RESEARCH LICENSE AGREEMENT, Copyright (c) 2026
Hangzhou Tongyi Laboratory Technology Co., Ltd. All Rights Reserved.
## What's next?
- **Use Pruna-Qwen-Image-2.1 to generate and edit images with Qwen-Image-2.1 in a few steps.**
- Compress your own models with [Pruna](https://github.com/PrunaAI/pruna) and give us a ⭐️ for more efficiency!
- Want to use our optimized image models right away? Check [P-Image-Ideogram](https://www.pruna.ai/p-image-ideogram) and [P-Image-Edit](https://www.pruna.ai/p-image-edit).
Try our models